A blood test that measures plasma phosphorylated tau 217 is capable of predicting future Alzheimer’s disease onset in cognitively normal older adults even when positron emission tomography scans do not show amyloid or tau build up in the brain.
“We used to think that positron emission tomography (PET) scan detection was the earliest sign of Alzheimer’s disease progression, revealing amyloid accumulation in the brain 10 to 20 years before symptoms appear,” said lead author Hyun-Sik Yang, MD, a neurologist with Mass General Brigham Neuroscience Institute, in a press statement.
“But now we are seeing that phosphorylated tau 217 (pTau217) can be detected years earlier, well before clear abnormalities appear on amyloid PET scans.”
In 2025, the FDA approved two blood tests for Alzheimer’s disease, one that compares the ratio of pTau217 to beta amyloid developed by Fujirebio and a pTau181 plasma test developed by Roche. However, both of these tests are only indicated for people who already have some symptoms of the condition.
The current study, published in Nature Communications, aimed to test whether pTau217 in the blood can forecast beta‑amyloid and tau build‑up in the brain before individuals become amyloid‑positive on PET scans.
Overall, 317 older adults, aged 72 years on average, from the Harvard Aging Brain Study were included in the study. About 60% were women. There were no signs of cognitive decline on enrollment, and the group had a high education level. The researchers followed up 245 people in the group with repeat amyloid scans for about six years on average.
The test was able to pick up cases where beta amyloid was visible on brain scans with a high level of accuracy. The study also showed that higher starting pTau217 levels predicted faster amyloid build‑up over time, even after accounting for age, sex, and APOE status
Centiloid units are the standard scale for amyloid on brain scans with 100 centiloids typical of full-blown disease. The team found that the test could also predict future amyloid buildup even if no signs could be seen on initial PET scans. Each one‑percentage‑point increase in pTau217 at baseline was linked to an extra 0.35 centiloid units of amyloid buildup per year. Notably, those with low pTau217 levels on enrollment were still amyloid negative on scans years later.
“What stood out in our study is that even when amyloid scans appear normal in the clinic, the pTau217 biomarker can identify individuals who later become amyloid-positive,” said Yang. “It also shows that those with low pTau217 levels are likely to stay amyloid-negative for several years.”
If you’re following AI news, you’re probably getting whiplash. AI is a gold rush. AI is a bubble. AI is taking your job. AI can’t even read a clock. The 2026 AI Index from Stanford University’s Institute for Human-Centered Artificial Intelligence, AI’s annual report card, comes out today and cuts through some of that noise.
Despite predictions that AI development may hit a wall, the report says that the top models just keep getting better. People are adopting AI faster than they picked up the personal computer or the internet. AI companies are generating revenue faster than companies in any previous technology boom, but they’re also spending hundreds of billions of dollars on data centers and chips. The benchmarks designed to measure AI, the policies meant to govern it, and the job market are struggling to keep up. AI is sprinting, and the rest of us are trying to find our shoes.
All that speed comes at a cost. AI data centers around the world can now draw 29.6 gigawatts of power, enough to run the entire state of New York at peak demand. Annual water use from running OpenAI’s GPT-4o alone may exceed the drinking water needs of 12 million people. At the same time, the supply chain for chips is alarmingly fragile. The US hosts most of the world’s AI data centers, and one company in Taiwan, TSMC, fabricates almost every leading AI chip.
The data reveals a technology evolving faster than we can manage. Here’s a look at some of the key points from this year’s report.
The US and China are nearly tied
In a long, heated race with immense geopolitical stakes, the US and China are almost neck and neck on AI model performance, according to Arena, a community-driven ranking platform that allows users to compare the outputs of large language models on identical prompts. In early 2023, OpenAI had a lead with ChatGPT, but this gap narrowed in 2024 as Google and Anthropic released their own models. In February 2025, R1, an AI model built by the Chinese lab DeepSeek, briefly matched the top US model, ChatGPT. As of March 2026, Anthropic leads, trailed closely by xAI, Google, and OpenAI. Chinese models like DeepSeek and Alibaba lag only modestly. With the best AI models separated in the rankings by razor-thin margins, they’re now competing on cost, reliability, and real-world usefulness.
The index notes that the US and China have different AI advantages. While the US has more powerful AI models, more capital, and an estimated 5,427 data centers (more than 10 times as many as any other country), China leads in AI research publications, patents, and robotics.
As competition intensifies, companies like OpenAI, Anthropic, and Google no longer disclose their training code, parameter counts, or data-set sizes. “We don’t know a lot of things about predicting model behaviors,” says Yolanda Gil, a computer scientist at the University of Southern California who coauthored the report. This lack of transparency makes it difficult for independent researchers to study how to make AI models safer, she says.
AI models are advancing super fast
Despite predictions that development will plateau, AI models keep getting better and better. By some measures, they now meet or exceed the performance of human experts on tests that aim to measure PhD-level science, math, and language understanding. SWE-bench Verified, a software engineering benchmark for AI models, saw top scores jump from around 60% in 2024 to almost 100% in 2025. In 2025, an AI system produced a weather forecast on its own.
“I am stunned that this technology continues to improve, and it’s just not plateauing in any way,” says Gil.
However, AI still struggles in plenty of other areas. Because the models learn by processing enormous amounts of text and images rather than by experiencing the physical world, AI exhibits “jagged intelligence.” Robots are still in their early days and succeed in only 12% of household tasks. Self-driving cars are farther along: Waymos are now roaming across five US cities, and Baidu’s Apollo Go vehicles are shuttling riders around in China. AI is also expanding into professional domains like law and finance, but no model dominates the field yet.
But the way we test AI is broken
These reports of progress should be taken with a grain of salt. The benchmarks designed to track AI progress are struggling to keep up as models quickly blow past their ceilings, the Stanford report says. Some are poorly constructed—a popular benchmark that tests a model’s math abilities has a 42% error rate. Others can be gamed: when models are trained on benchmark test data, for example, they can learn to score well without getting smarter.
Because AI is rarely used the same way it’s tested, strong benchmark performance doesn’t always translate to real-world performance. And for complex, interactive technologies such as AI agents and robots, benchmarks barely exist yet.
AI companies are also sharing less about how their models are trained, and independent testing sometimes tells a different story from what they report. “A lot of companies are not releasing how their models do in certain benchmarks, particularly the responsible-AI benchmarks,” says Gil. “The absence of how your model is doing on a benchmark maybe says something.”
AI is starting to affect jobs
Within three years of going mainstream, AI is now used by more than half of people around the world, a rate of adoption faster than the personal computer or the internet. An estimated 88% of organizations now use AI, and four in five university students use it.
It’s early days for deployment, and AI’s impact on jobs is hard to measure. Still, some studies suggest AI is beginning to affect young workers in certain professions. According to a 2025 study by economists at Stanford, employment for software developers aged 22 to 25 has fallen nearly 20% since 2022. The decline might not be pinned on AI alone, as broader macroeconomic conditions could be to blame, but AI appears to be playing a part.
Employers say that hiring may continue to tighten. According to a 2025 survey conducted by McKinsey & Company, a third of organizations expect AI to shrink their workforce in the coming year, particularly in service and supply chain operations and software engineering. AI is boosting productivity by 14% in customer service and 26% in software development, according to research cited by the index, but such gains are not seen in tasks requiring more judgment. Overall, it’s still too early to understand the bigger economic impact of AI.
People have complicated feelings about AI
Around the world, people feel both optimistic and anxious about AI: 59% of people think that it will provide more benefits than drawbacks, while 52% say that it makes them nervous, according to an Ipsos survey cited in the index.
Notably, experts and the public see the future of AI very differently, according to a Pew survey. The biggest gap is around the future of work: While 73% of experts think that AI will have a positive impact on how people do their jobs, only 23% of the American public thinks so. Experts are also more optimistic than the public about AI’s impact on education and medical care, but they agree that AI will hurt elections and personal relationships.
Among all countries surveyed, Americans trust their government least to regulate AI appropriately, according to another Ipsos survey. More Americans worry federal AI regulation won’t go far enough than worry it will go too far.
Governments are struggling to regulate AI
Governments around the world are struggling to regulate AI, but there were some minor successes last year. The EU AI Act’s first prohibitions, which ban the use of AI in predictive policing and emotion recognition, took effect. Japan, South Korea, and Italy also passed national AI laws. Meanwhile, the US federal government moved toward deregulation, with President Trump issuing an executive order seeking to handcuff states from regulating AI.
Despite this federal action, state legislatures in the US passed a record 150 AI-related bills. California enacted landmark legislation, including SB 53, which mandates safety disclosures and whistleblower protections for developers of AI models. New York passed the RAISE Act, requiring AI companies to publish safety protocols and report critical safety incidents.
But for all the legislative activity, Gil says, regulation is running behind the technology because we don’t really understand how it works. “Governments are cautious to regulate AI because … we don’t understand many things very well,” she says. “We don’t have a good handle on those systems.”
Background: An increasing number of rehabilitation technologies are being developed to support upper limb rehabilitation after stroke, with smart textile solutions for surface electromyography (sEMG) emerging as a promising approach. Early end-user involvement is crucial for developing user-friendly and clinically valid rehabilitation tools. Objective: This study aims to refine and evaluate the prototype design and usability of a smart textile biofeedback system for self-administered upper limb training after stroke. Methods: The training system includes a knitted smart textile sleeve with integrated electrodes over the forearm muscles, an sEMG unit, and tablet-based biofeedback software. An iterative co-design process was followed, including initial testing, demonstration sessions with end users (9 clinicians and 10 individuals with stroke), and a final evaluation of the co-design process. Participants’ experiences were gathered through semistructured interviews, analyzed using content analysis, and the User Experience Questionnaire. The co-design team included experts in stroke rehabilitation, textile engineering, biomedical engineering, software development, and human factors, as well as a research partner with lived experience after stroke. Results: The perspectives of the end users and the expert team were collectively integrated into prototype refinements of the sleeve and training software to meet the needs of the intended target group. The experiences of end users formed 2 main categories: “This could be an exciting new training tool for stroke rehabilitation” and “The tool works well, but some changes could enhance independent training.” End users found the smart textile sleeve and biofeedback system easy to use and saw potential for integrating it into their training routines. Both end-user groups rated the system as attractive, stimulating, and novel. Conclusions: The results of this study establish a necessary ground toward the development of a smart textile sEMG biofeedback system for self-administered upper limb training after stroke. Findings from the co-design process support the continued development and evaluation of the system as a self-administered upper limb training tool for individuals living with stroke.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/09868209cfa3cec73d3f73d20963ee99" />
Background: Stairclimbing wheelchairs offer enhanced mobility for users navigating multilevel environments, yet limited research addresses the ergonomics of lever propulsion-based stair climbing mechanisms. Comprehensive ergonomic assessment integrating both subjective user feedback and objective biomechanical analysis is essential for optimizing assistive device design for comfort and usability. Objective: This pilot study aims to assess the ergonomic design of a transformable stair-climbing wheelchair through a dual-methodology approach, evaluating plane surface movement accessibility and quantifying muscle activation patterns during lever-propelled stair-climbing operations using surface electromyography (sEMG). Methods: This 2-part study involved anthropometric measurements from 20 male participants to establish design parameters using 5th and 95th percentile values. Part A assessed plane surface movement with 9 participants (7 healthy, 2 with paraplegia) navigating a simulated urban course featuring a 5° ramp, a 90° turn, and narrow passages across 3 trials. Task completion times and subjective ride easiness ratings were recorded. Part B used a Taguchi-based fractional factorial design to evaluate 3 ergonomic factors, including torso angle (λ), lever distance (L), and lever orientation (ψ), across 7 healthy participants. Maximum voluntary contraction (MVC) was measured for 4 muscles, including biceps brachii long head (BBL), triceps brachii long head (TBL), brachioradialis, and posterior deltoid (PDT). Results: In Part A, the ramp and 90° turn proved most challenging due to the wheelchair’s 65 kg weight and large turning radius (~1450 mm). Driving control scored highest (6/10), while comfort scored lowest due to the tilted seat design. In Part B, a straight torso (λ=0°) consistently reduced muscle strain, particularly for brachioradialis. A lever distance of approximately 50 mm and a neutral to slightly supinated orientation (ψ=0°-30°) optimized muscle effort. Interaction effects revealed high strain configurations (λ=45°; L=100 mm; ψ=−30°) exceeding 75 MVC, while optimal settings reduced strain to approximately 50 MVC. Conclusions: Optimal ergonomic parameters of λ=0°, L=37.5 mm, and ψ=15° are recommended to minimize fatigue and enhance user comfort. Design improvements should prioritize weight reduction, compact form factor for maneuverability, and adjustable seat tilt. The modular wheelchair design permits customization for diverse user populations. Future research should include larger, gender-diverse participant groups and real-world validation studies.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/c6e4d2f2e2e8a4f16fcea3fc762bfa0d" />
Background: Wellness tourism increasingly incorporates short yoga sessions for stress management, yet evidence on their immediate physiological and emotional responses remains limited. Objective: This exploratory pilot study aimed to generate preliminary data on acute physiological and emotional responses to a single 24-minute yoga session (breathing, postures, and meditation) compared with quiet sitting in novice practitioners. Methods: In this single-center, randomized waitlist-controlled exploratory pilot study (1:1 allocation), 19 university-affiliated adults with self-reported daily stress and no prior guided yoga experience were allocated to an immediate 24-minute yoga session (n=10) or quiet sitting (n=9). The primary outcome was change in salivary cortisol from baseline to postintervention. Secondary outcomes included salivary alpha-amylase, heart rate (Apple Watch [Apple Inc], subset n=12), and real-time emotional indices (stress, calmness, and concentration) measured by a commercial single-channel electroencephalogram (EEG) device (Kansei Analyzer [Dentsu ScienceJAM], subset n=8). Data were analyzed using change scores relative to the breathing phase, with between-group comparison performed by independent tests or multivariable linear regression adjusted for age, sex, and baseline values as appropriate. Results: No significant between-group differences were observed for salivary cortisol or alpha-amylase. In the yoga group, heart rate increased during postures and remained mildly elevated during meditation relative to the breathing phase, consistent with mild physical exertion. Exploratory individual EEG analyses suggested reduced stress and increased concentration during breathing and meditation phases in some participants. Conclusions: In this small exploratory pilot study, a single 24-minute yoga session did not significantly alter salivary stress biomarkers at the group level. However, it induced measurable cardiovascular activation and heterogeneous EEG-derived emotional responses. These hypothesis-generating findings demonstrate marked interindividual variability, suggesting the need for larger validation studies with improved control conditions.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/4888ec268eb7bb97167592e681af43d2" />
Background: Translation of medical consultation summaries is essential for equitable health care communication in culturally and linguistically diverse populations. While machine translation (MT) tools and large language models (LLMs) are widely accessible, their feasibility and safety for health care contexts remain underexplored. Objective: This pilot study investigates the feasibility and limitations of using LLMs and traditional MT tools to translate medical consultation summaries from English into the most common languages other than English spoken in Australia—Arabic, Chinese (simplified written form), and Vietnamese. Methods: Two simulated summaries—a simple patient-facing summary and a complex clinician-oriented interprofessional letter—were translated using 3 LLMs (GPT-4o, Llama-3.1, and Gemma-2) and 3 MT tools (Google Translate, Microsoft Bing Translator, and DeepL). Translations were benchmarked against professional third-party interpreter translations using Bilingual Evaluation Understudy, Character-level F-score, and Metric for Evaluation of Translation with Explicit Ordering metrics. Results: The translation performance varied across languages, tools, and summary complexity when assessed using automatic evaluation metrics. Traditional MT tools outperformed LLMs on surface-level metrics, while LLMs showed relative strengths in semantic similarity for Vietnamese and Chinese. Arabic translations improved with complex input, suggesting morphological advantages. The metric-based evaluation highlighted feasibility but also risks, particularly in Chinese clinical contexts. Conclusions: This pilot study provides formative evidence of opportunities and limitations in applying artificial intelligence translation for health care communication. Findings underscore the importance of human oversight; domain-specific evaluation metrics; and further formative and clinical research to guide the safe, equitable use of artificial intelligence translation tools.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/b86925d16f121fdeb31e2fefcf1227ba" />
Background: Cyberaggression poses a growing threat to mental health, contributing to increased distress, reduced self-esteem, and other adverse psychosocial outcomes. Although bystander intervention can mitigate the escalation and impact of cyberaggression, individuals often lack the confidence, strategies, or language to respond effectively in these high-stakes online interactions. Advances in generative artificial intelligence (AI) present a novel opportunity to facilitate digital behavior change by assisting bystanders with contextually appropriate, theory-informed intervention messages that promote safer online environments and support mental well-being. Objective: This mixed methods design study aimed to explore the feasibility of using generative AI to support bystander intervention in cyberaggression on social media. Specifically, we examined whether AI can generate effective responses aligned with established intervention strategies and how these responses are perceived in terms of their potential to de-escalate online harm and foster behavior change. Methods: We collected 1000 real-world cyberaggression examples from public social media datasets and generated bystander intervention responses using 3 distinct prompt strategies: a generic policy reminder, a baseline GPT prompt, and a theory-driven GPT prompt (AllyGPT). To evaluate the responses, we conducted computational linguistic analyses to assess their psycholinguistic features and carried out a mixed methods evaluation. Three trained coders rated each message on favorability, conversational impact, and potential to change behavior and later participated in semistructured interviews to reflect on their evaluation process and perceptions of intervention effectiveness. Results: Linguistic analyses revealed that baseline GPT responses exhibited more emotionally positive and authentic language compared to AllyGPT responses, which showed a more analytical and assertive tone. Policy reminder messages were linguistically rigid and lacked emotional nuance. Human evaluation results showed that AllyGPT responses received the highest effectiveness ratings for low-incivil cyberaggression cases in 2 dimensions (favorability and changing behavior), and baseline GPT works better for mid and high levels for all effectiveness dimensions. For medium- and high-incivility aggressions, baseline GPT responses received the highest ratings across all 3 dimensions of effectiveness (favorability, discussion-shifting potential, and likelihood of changing bullying behavior), followed by AllyGPT, with policy reminders rated lowest. Qualitative feedback further emphasized that baseline GPT responses were perceived as natural and inclusive, while AllyGPT responses, although grounded in psychological theory, were sometimes viewed as overly direct. Policy reminders were considered clear but lacked persuasive impact. Conclusions: Our work showed that designing effective AI-generated bystander interventions requires a deep sensitivity to platform culture, social context, and user expectations. By combining psychological theory with adaptive, conversational design and ongoing feedback loops, future systems can better support bystanders, delivering interventions that are not only contextually appropriate but also socially resonant and behaviorally impactful. As such, this work serves as a foundation for scalable, human-centered AI systems that promote safer online spaces and users’ mental well-being.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/2902e66b1ac5ac34f57f42bbc6adfe75" />
<strong>Background:</strong> Over 2.1 million adolescent and young adult cancer survivors (AYACS) live in the United States. Recent estimates suggest that up to one-third of AYACS experience major depressive disorder. Although several efficacious evidence-based interventions are available to manage symptoms of depression, these interventions are often inaccessible to AYACS who have many competing commitments. Digital mental health tools hold promise for this population; however, only a few have been tailored to meet the unique needs of AYACS, and findings to date have yielded mixed results. <strong>Objective:</strong> This study aims to obtain feedback from AYACS on a mid-fidelity prototype of a depression self-management tool being tailored for AYACS. <strong>Methods:</strong> Individuals with a history of cancer diagnosed at age 12 or older who were between the ages of 15 and 39 and had completed primary treatment were identified through a review of medical records from a comprehensive cancer center in the Southeastern United States. Potentially eligible participants were contacted by study staff to conduct additional screening and obtain informed consent via REDCap (Research Electronic Data Capture; Vanderbilt University). Upon enrollment, participants provided demographic and clinical information, as well as their availability for an interview. The principal investigator (KMI) conducted semistructured individual interviews with consented AYACS. Most of the interview was dedicated to showing participants the mid-fidelity prototype of the tool, explaining how the prototype might work, and requesting targeted feedback. Demographic and clinical characteristics, as well as some aspects of feedback on the prototype, were summarized using descriptive statistics. Interviews were audio- and video-recorded and transcribed. The transcriptions underwent rapid qualitative analysis guided by the Rigorous and Accelerated Data Reduction technique. <strong>Results:</strong> A total of 14 AYACS (n=9, 64%, female; n=9, 64%, white; ages 15-38) completed an individual interview. Participant preferences for mood tracking, content presentation, user input, and duration of use were captured qualitatively but analyzed quantitatively. For example, most participants (n=10, 71%) indicated that they preferred a mood-tracking option that included emojis and would be willing to track their mood at least once per day (n=11, 79%). Participant preferences captured qualitatively fell into 4 themes: (1) features to promote user engagement (eg, the use of gamification); (2) tailored content presentation (eg, authenticity in the portrayal of the cancer experience); (3) perceived usability (eg, simplifying user input); and (4) interface design (eg, implementing a coherent design theme and color scheme). <strong>Conclusions:</strong> Findings indicated that AYACS highly value personalization, flexibility, and peer support in digital interventions. Based on insights obtained during individual interviews, a working prototype was developed by reprogramming an existing digital tool. Qualitative and quantitative findings informed modifications to the existing digital tool. The working prototype will next undergo evaluation as part of a pilot full-factorial trial.
Immune system aging, known as immunosenescence, is associated with changes in immune cell composition and function that increase susceptibility to disease. The results of a study by researchers at the Barcelona Supercomputing Center – Centro Nacional de Supercomputación (BSC–CNS) have now shown that immunological aging follows different dynamics between men and women.
The team analyzed single-cell RNA sequencing data from the peripheral blood mononuclear cells (PBMCs) of 982 female and male donors across adulthood, to identify cells and genes involved in immunosenescence, and potentially provide a molecular explanation for the differences that had previously only been observed globally in the population.
“Until now, most studies analyzed the immune system based on the average of many cells at once, which makes it difficult to capture the progressive effects of aging,” said Maria Sopena-Rios, PhD. “With cell-by-cell analysis and a much larger sample, we were able to detect these patterns and compare them robustly between biological sexes.” Their strategy identified sex-related differences in immunological aging may help to explain why women have an 80% higher incidence of autoimmune diseases than do men, and why men are more likely than women to develop hematological cancers and chronic infections.
Sopena-Rios is co-first author of the team’s published paper in Nature Aging, titled “Single-cell analysis of the human immune system reveals sex-specific dynamics of immunosenescence,” in which the investigators concluded “Together, our findings provide a high-resolution map of sex-specific immune aging and lay the groundwork for tailored sex-specific strategies to monitor and improve immune health across the lifespan.”
Statistics show clear differences in the population’s immune system according to sex: men are more susceptible to infections and cancers, while women have stronger immune responses, which translate, for example, into better responses to vaccines. Even so, with a more reactive immune system, the probability of the body attacking itself also increases, causing 80% of autoimmune disease development to occur in women. In this context, understanding the aging of the immune system is key since, with age, the composition of immune cells changes and their protective functions deteriorate, causing a greater susceptibility to diseases.
Aging of the immune system, or immunosenescence, refers to “… the gradual decline of the immune system, which predisposes to multiple diseases, including infection, cancer, and autoimmune and vascular diseases,” the authors wrote. “Importantly, the age-related decline of the immune system involves both changes in the composition of immune cell populations and molecular alterations.” However, understanding how sex influences this profound transformation was not possible until now. “…how biological sex shapes immune aging at the cellular level remains poorly understood,” the investigators stated.
For their reported study, the team analyzed blood samples from nearly 1,000 people of different ages covering the entire adult life, and carried out single-cell RNA sequencing to analyze the activity of 20,000 genes in more than one million blood cells. This approach allowed them to identify how the immune system changes over the years and detect clear differences between sexes. Although evidence existed that the immune system ages differently according to sex, women have been traditionally underrepresented in studies, the authors comment. This is the first time that large quantities of samples were analyzed with a balance between men and women, a fact that was decisive in obtaining these results.
“Many studies still do not take sex into account in their analyses, or directly only use data from men, so they leave key questions unanswered,” said study director Marta Melé, PhD, leader of the Transcriptomics and Functional Genomics group at BSC. “Our research was born precisely from this need and combines a scientific outlook with a sex perspective, inclusive data, and great computational power.”
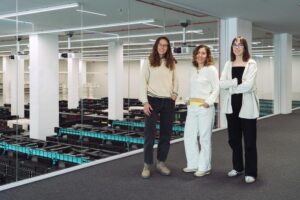
BSC researchers Aida Ripoll-Cladelles (left), Marta Melé (center) and Maria Sopena-Rios (right) in front of MareNostrum 5 supercomputer. [Mario Ejarque / BSC–CNS]
The results revealed that women present more pronounced changes in the immune system with age, with an increase in inflammatory immune cells. This finding could help explain why autoimmune diseases are mainly developed by women, especially at advanced ages, as well as the worsening of certain inflammatory pathologies after menopause.
“Female individuals typically mount stronger immune responses, enhancing resistance to infections and vaccine efficacy, but also contributing to an 80% higher incidence of autoimmune diseases,” the authors noted. “Aging further increases autoimmune risk, and we showed that this is accompanied by the female expansion of cell subpopulations with pivotal roles in autoimmunity.”
On the other hand, the study found that changes associated with immune system aging observed in men are globally less extensive, but an increase in certain blood cells presenting pre-leukemia alterations was observed, a fact that could explain why some blood cancers are more frequent in older men. “Male immune aging is less transcriptionally pronounced, with fewer sex-specific signatures and subtler shifts in immune cell abundance,” the investigators wrote. “.… a subset of male participants shows an age-associated expansion of a B cell population linked to an asymptomatic precursor state of chronic lymphocytic leukemia … Our findings suggest that male immune remodeling may contribute to increased vulnerability to hematological malignancies and chronic infections.”
To manage, process, and analyze a volume of data of this magnitude, the scientific team required the use of advanced computational methods that had never been applied to such complex data sets, with the MareNostrum 5 supercomputer as a key piece to make possible a study that would not have been viable without high-performance computing infrastructure.
With these discoveries, the study establishes the bases for incorporating biological sex as a key variable in precision medicine for aging. The identification of sex-specific aging cells and biomarkers opens the door to the development of preventive, diagnostic, and therapeutic strategies better adapted to women and men, contributing to more individualized and equitable healthcare in an increasingly aging population.
“The immune system plays a fundamental role throughout the organism; therefore, the differences we observed have a very important generalized impact on the entire body. Better understanding the aging of the immune system can help us understand processes that go beyond the blood and affect multiple tissues,” noted co-first author Aida Ripoll-Cladellas, PhD.
Treating aging as a homogeneous process in the entire population hides key biological differences, and understanding how it varies between women and men, the authors concluded, will be essential to improve immune health and promote healthy aging within everyone’s reach. “Stratifying analyses according to sex uncovers key sex-specific features of immunosenescence that may otherwise be misinterpreted as shared effects,” they stated. “This underscores the importance of considering sex as a biological variable to ensure biologically accurate conclusions. Ultimately, our findings lay the foundation for sex-tailored strategies to monitor immune aging and mitigate the burden of age-related immune dysfunction.”