

AI Model Predicts Cancer Treatment Response from Tumor Genotype

Researchers at University of California, San Diego have developed a new artificial intelligence (AI) model that can translate a tumor’s complex genetic profile into predictions about how that cancer may respond to treatment. The foundation model, called MutationProjector, was trained on genomic data from more than 30,000 tumors across 10 solid cancer types, and validated through testing across multiple independent patient cohorts. Led by Trey Ideker, PhD, professor of medicine at UC San Diego School of Medicine and director of the Big Data Institute at the University of Oxford, the researchers say the model offers a new framework for connecting cancer mutations to the biological pathways that drive treatment response.

“Genetic sequencing is already routine in cancer care, but we still struggle to fully interpret the many mutations found in a patient’s tumor,” said Ideker, who also holds a second appointment at UC San Diego Jacobs School of Engineering and is a member of UC San Diego Moores Cancer Center. “Our goal with MutationProjector was to build a general-purpose model that can learn from tens of thousands of tumor genomes and turn those mutation patterns into more precise predictions about treatment response.”

Ideker is co-senior and co-corresponding author of the team’s published paper in Cancer Discovery, titled “A foundation model of cancer genotype enables precise predictions of therapeutic response,” in which the authors stated, “These results establish a unifying framework for connecting tumor genotypes to biological mechanisms and therapeutic outcomes.”

Following a cancer diagnosis, one of the next steps is often genetic testing, which helps doctors classify the tumor and decide which treatments to pursue. “DNA sequencing panels—and in particular those that broadly identify alterations in cancer-associated genes—have been widely adopted in the clinic due to their relatively low cost, rapid turnaround, and established relevance to treatment outcomes,” the authors explained.
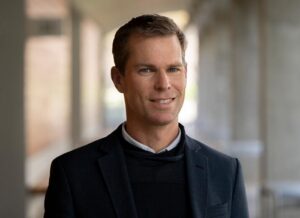
Trey Ideker is a professor of medicine at UC San Diego School of Medicine and director of the Big Data Institute at the University of Oxford. [Erik Jepsen / UC San Diego]

However, while genetic testing is relatively low cost, fast, and has a strong track record in cases where validated genetic biomarkers are available, those cases remain limited, because this type of treatment stratification is currently based on only a small number of known biomarkers. Today, only about 8% of cases are successfully matched to an FDA-approved therapy on the basis of genetics and usually on the basis of a single gene, the team continued. “While this situation may reflect the incomplete scope of genes covered by current sequencing panels, it clearly also reflects a fundamental lack of knowledge about how gene mutations should be interpreted.”

They suggest that an “average” tumor has approximately 11 distinct genetic alterations identified by clinical sequencing, representing a potentially rich source of molecular information, if this information could be used to help select treatment. One of the challenges to matching cancer mutations with treatment outcomes is that most mutations are rare, the investigators pointed out. Another is that individual biomarkers do not function in isolation, but act together to influence drug response.

Unlike existing approaches that rely on a small number of biomarkers, MutationProjector analyzes the broader combination of genetic alterations present in a tumor. The model then uses this information to generate a compact representation of the tumor’s biological state, helping researchers interpret which molecular pathways may be disrupted and, by extension, which treatments may be most effective. “Foundation models, which are pre-trained on large datasets and then applied to solve diverse new challenges with relatively few samples, are especially well positioned to advance precision oncology,” Ideker and team noted.

The investigators trained their foundational model, MutationProjector, using genetic profile data from more than 30,000 tumors samples across different cancer types. They then showed that across several independent cohorts of cancer patients, including those with bladder cancer, lung cancer and melanoma, MutationProjector matched or exceeded existing methods for predicting response to common immunotherapy and chemotherapy treatments. The model also identified both known and unexpected biomarkers associated with treatment outcomes, which could help improve current approaches to genetic testing and patient stratification.

“When applied to predict immunotherapy or chemotherapy resistance across multiple cancer types and cohorts, MutationProjector achieves or exceeds state-of-the-art performance in all contexts,” the team wrote. “It identifies unexpected biomarkers, including KMT2D mutation in immunotherapy sensitivity and joint alteration of SMARCA4 and STK11 in immunotherapy resistance.”

JungHo Kong, PhD, first author of the study and a postdoctoral researcher in the department of medicine at UC San Diego School of Medicine, said, “Many cancer mutations are individually rare, which makes them difficult to study one at a time. By pretraining on a large collection of tumors and integrating molecular network knowledge, MutationProjector can detect patterns that would be easy to miss with conventional biomarker approaches. That gives us a way to move from long lists of mutations toward a more functional understanding of the tumor.”
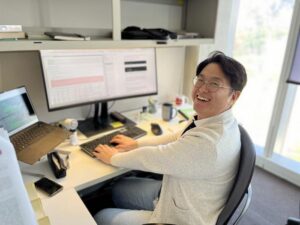
First study author JungHo Kong, shown here, is a postdoctoral researcher at UC San Diego School of Medicine. [UC San Diego Health Sciences]

The researchers emphasize that the model was designed not only to make predictions, but also to provide insight into why those predictions are made, which could help when refining biomarkers and treatment strategies. This interpretability is especially important in precision oncology, where clinicians need to understand how tumor genotypes relate to treatment decisions.

The team also hopes to expand the model to additional cancer types and data sources, including international cancer genome datasets and other forms of clinical information, such as imaging, transcriptomics, and electronic health records. “While 30,000+ genomes representing 10 solid tumor types were considered in our study, numerous additional tumor samples are available for expansion of MutationProjector to tumor types such as pancreatic cancer, prostate cancer or sarcomas,” the authors said. “Other future studies should explore the extent to which the MutationProject concept can be applied to further clinical tasks of interest, including application to liquid biopsies of circulating tumor DNAs for early cancer detection.”

Ideker added, “Our results suggest that tumor genome foundation models may help extend the clinical value of sequencing beyond a handful of well-known genes. This could support a more comprehensive and biologically grounded approach to precision oncology.”

The post AI Model Predicts Cancer Treatment Response from Tumor Genotype appeared first on GEN – Genetic Engineering and Biotechnology News.
MOSAIC: Multimodal In Vivo Imaging Data Powers AI Models for Living Systems

In a new study published in Nature Methods titled, “A multimodal adaptive optical microscope for in vivo imaging from molecules to organisms,” researchers from University of California, Berkeley present high-powered microscopes that can track the development of live specimens, including cell movement through tissue, the evolution of internal cellular structures, and shuttling of proteins and other molecules within the cell. The system, named Multimodal Optical Scope with Adaptive Imaging Correction (MOSAIC), has been implemented in more than a dozen worldwide labs over the past six years. 

“Life has to be studied in living tissue, holistically, and over fast timescales and for long periods of time,” said Eric Betzig, PhD, professor of molecular and cell biology at UC Berkeley, 2014 Nobel Prize in Chemistry, and co-corresponding author on the study. “You can’t study something as complex as a cell or organism just by looking at the parts individually—there are something like 40 million protein molecules alone of 20,000 different types.” 

The microscope uses a large “vision” language model (LVLM), similar to ChatGPT, to measure petabytes of data, the equivalent of about 500 billion pages of text.  

Betzig, who is also a Howard Hughes Medical Institute (HHMI) investigator, refers to the imaging data as five-dimensional (5D) composed of three spatial dimensions, plus time and color. The color comes from fluorescent labels that allow scientists to track multiple subcellular structures simultaneously, such as organelles, membranes, the cytoskeleton and more, as they migrate, change shape, divide and interact over time. 

In one video, the authors capture a zebrafish regrowing its tail fin. The video revealed tiny events inside living tissue that are normally difficult to visualize, such as cells near the wound releasing small communication packets, microscopic fibers beneath the skin shifting as the tissue repaired itself, two repair cells fusing together and a red blood cell briefly getting trapped as new blood vessels were remodeled. 

Ian Swinburne, PhD, assistant professor of molecular and cell biology at UC Berkeley and collaborator on the work, emphasizes that there’s a wealth of information in these large movies across scales, but it can be difficult for a very well-trained biologist to interrogate the data.

“AI can help us interface with the data and ask or answer questions more easily. Like, ‘How many macrophages are crawling into my tissue during an infection?’ or ‘Can I predict when a cell’s going to start leaving its organ?’ That happens in development but also in cancer during metastasis,” said Swinburne. 

Building an LVLM or AI that can handle petabytes of imaging data is a main focus of Berkeley’s Advanced Bioimaging Center, which hopes to create a first-of-its-kind Cell Observatory. 

“The impact of MOSAIC will be minimal until we build an AI model that can deal with the data that comes out of those systems. We basically have a gold mine, but we have no ability to get the gold out,” said Srigokul “Gokul” Upadhyayula, PhD, assistant professor in residence of cell biology, development and physiology at UC Berkeley. “The primary output of our Cell Observatory Initiative will be an AI mind that’s able to be our scientific partner in extracting these observations.” 

The post MOSAIC: Multimodal <i>In Vivo</i> Imaging Data Powers AI Models for Living Systems appeared first on GEN – Genetic Engineering and Biotechnology News.

The Download: puncturing the AI jobs panic

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology.

A reality check on the AI jobs hysteria

Despite the growing hysteria over AI’s threat to white-collar jobs, there’s still scant evidence that the technology has had a large-scale impact on the labor market.

Analysis of US labor data shows that unemployment in occupations most exposed to AI is actually lower than in less-exposed jobs. There are also no signs that large numbers of workers are shifting from AI-threatened professions into supposedly safer manual-labor jobs.

It’s true that things aren’t great in the job market—but the question is why. Here’s what the data really says about AI and jobs.

—David Rotman

Opinion: It’s time to address the looming crisis in entry-level work

—Georgios Petropoulos, an assistant professor at the USC Marshall School of Business

AI has not yet produced mass unemployment. But it may be quietly weakening the first rung of the career ladder.

A recent Stanford study found that young workers in AI-exposed occupations suffered a sharp decline in employment after the spread of generative AI. The same pattern didn’t appear in low-exposure jobs, suggesting AI is replacing junior tasks that once gave young workers their first foothold.

It’s time to rethink how we train, prepare, and support young people entering the workforce. Read this op-ed on how job seekers, businesses, and society can adapt.

The must-reads

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.

1 The Pope has called for governments to regulate AI 
In his first major teaching document, Pope Leo said AI must be “disarmed.” (BBC)
+ He warned that AI fuels war and misinformation. (CNN)
+ But could also “open up a horizon extending in all directions.” (Engadget)
+ Anthropic cofounder Chris Olah also spoke at the event. (Reuters $)

2 SpaceX has launched its biggest and most powerful rocket
The Starship V3 made its test flight debut two days after Elon Musk announced SpaceX’s IPO.(Guardian)+ SpaceX pulled off the launch, but not the landing. (Ars Technica)
+ The rocket could be key to SpaceX’s valuation. (Fortune $)
+ But rivals to the company are rising. (MIT Technology Review)

3 Huawei says it can make industry-leading chips within five years
The Chinese tech giant announced a breakthrough in chip design. (Reuters $)
+ Its progress underscores Beijing’s push to neutralize US sanctions. (NBC)
+ Chinese chip stocks rallied after the announcement. (Bloomberg $)

4 A new vaccine may protect against the Ebola strain behind the current crisis
Tests have shown promising results for the mRNA vaccine. (New Scientist)
+ Another Ebola vaccine that could be ready for trials in months. (BBC)
+ But vaccines face a new problem: their name. (MIT Technology Review)

5 A swimmer broke a world record at the ‘Steroid Olympics’
Athletes at the Enhance Games were encouraged to take dope. (Wired $)
+ Silicon Valley elites have backed the competition. (WP $)
+ Which fits right into 2026’s longevity vibes. (MIT Technology Review)

6 The EU plans to fine Google a massive antitrust penalty
For allegedly favoring its own services in search results. (CNBC)
+ It would be the largest penalty for breaching the Digital Markets Act. (Reuters $) 

7 US quantum computing subsidies may not be legal
Congressional critics say the funding has been misused. (Ars Technica)

8 AI is minting new billionaires—and workers want their share
The Samsung labor showdown reflects global concerns. (Rest of World)

9 China has launched artificial human embryos into orbit
To find out whether we can reproduce beyond Earth. (Gizmodo)

10 Jony Ives has designed Ferrari’s first fully-electric car
The legendary Apple designer has created a polarizing aesthetic. (FT $) 

Quote of the day

“Technology is never neutral, because it takes on the characteristics of those who devise, finance, regulate, and use it.” 

—Pope Leo issues a warning about AI in his first encyclical letter, entitled ‘Magnifica humanitas: On Safeguarding the Human Person in the Time of Artificial Intelligence.”

One More Thing

portrait of Monica Sanders

ALYSSA SCHUKAR


How climate vulnerability and the digital divide are linked

In Anacostia, a historic African-American section of Washington, DC, Monica Sanders is measuring Wi-Fi speeds. It’s below the FCC’s minimum to qualify as a broadband service. She then checks the temperature: 46.9 °F.

Sanders, an adjunct professor of law at Georgetown University, frequently records this combination of weak internet access and environmental conditions. Her work shows how underinvestment in infrastructure can leave underserved communities more exposed to climate risks like extreme heat and flooding.

Discover how the digital divide is shaping climate vulnerability in the US.

—Colleen Hagerty

We can still have nice things

A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.)

+ Here’s a joyful way to settle sibling squabbles: a mandatory dance-off.
+ Build the metropolis of your dreams in this browser-based city simulation game.
+ Watch this hypnotic tiny train move in a perfect, endless loop on a rotating turntable.
+ Take a nostalgic look at early computing history with this curated gallery of vintage punch cards.

It’s time to address the looming crisis in entry-level work.

Artificial intelligence has not so far produced a clean story of mass unemployment. Aggregate employment in developed countries remains broadly stable, and recent assessments have found limited evidence that AI has shifted the headline numbers. But a troubling change may be hiding beneath the surface: the quiet weakening of the first rung of the career ladder.

The most worrisome evidence is showing up exactly where we should expect it first: in early-career hiring. A working paper released in November 2025 by the Stanford Digital Economy Lab found that workers aged 22 to 25 in the most AI-exposed occupations experienced a 16% relative decline in employment after the spread of generative AI, even after controlling for other factors that might affect firms’ employment decisions. An Anthropic report from March 2026 provides suggestive evidence that led to a similar conclusion.

More experienced workers in those same occupations did not suffer the same decline. Employment is not also declining in the entry-level jobs with low AI exposure. The concern is specific to early-career jobs that are exposed to AI.

That is not a minor signal. It suggests that firms may be using AI to substitute for the junior tasks through which people traditionally gain their first foothold—at least for those in jobs where generative AI is used extensively, like software developers, customer service representatives, computer programmers, and information systems managers.

The time is now to make changes in the way we train, prepare, and support young people who are about to enter the workforce. Educational institutions need to reorient for the era of an AI-augmented workforce. Governments must incentivize businesses to hire and train early-career workers. Businesses, in turn, need to recognize the importance of developing a long-term workforce experienced in AI—a process that begins with entry-level workers. And students themselves should take on the responsibility of not only becoming AI fluent but learning how to apply that knowledge in various fields.

In short, we must change the way we have traditionally thought of entry-level work.

This is especially true because the broader labor market for recent graduates is also softening. The Federal Reserve Bank of New York reported that in the fourth quarter of 2025, the unemployment rate for recent college graduates rose to 5.6%, while the underemployment rate (the share of graduates working in jobs that typically do not require a college degree) reached 42.5%, its highest level since the covid pandemic. No single statistic can prove that AI is the sole cause of that deterioration. Hiring in general is way down post-pandemic, and young people are particularly vulnerable to the slowdown. But it would be a mistake to ignore the possibility that AI is accelerating an already difficult transition from school to work.

Behind these statistics is a great deal of personal distress. Recent graduates today often submit hundreds of applications before they receive a single offer, and surveys consistently find elevated rates of anxiety, financial precarity, and burnout among young workers in extended job searches. If AI quietly closes the door on typical early jobs, people will pay the price in delayed independence, postponed family formation, and the sense that their first serious professional efforts have been refused.

It also matters because entry-level jobs are part of the economy’s training system. Junior analysts learn which numbers can be trusted. Young software developers learn how production systems fail. New marketers learn how customers behave outside the neat language of dashboards. Early-career legal and financial staff learn how rules, judgment, deadlines, and human relationships actually interact. If AI absorbs more of the drafting, triage, coding, summarizing, and administrative preparation that once helped train entry-level workers, firms may become more efficient in the short run while society becomes less capable in the longer run.

The right way to improve the skills of young workers is not to tell them, “Learn to code.” That advice, which shaped more than a decade of federal initiatives and university expansion, rested on the premise that coding was a stable, scalable skill almost anyone could learn and parlay into a middle-class job. The premise no longer holds. The layer of work AI handles well—translating a specification into routine code, reproducing standard patterns, debugging predictable errors—is precisely the layer that “learn to code” programs were built around.

Supervising AI systems in their work is now a much more relevant skill. So understanding the outputs AI systems produce will become very important.

To help people develop such skills, we should require universities, community colleges, and professional programs to embed AI literacy, data literacy, prompt-based workflow skills, verification skills, and domain judgment into ordinary degrees. Every graduate should know how to use AI tools, check their output, understand their limits, and combine them with human expertise. This matters even for graduates entering occupations that look relatively safe from AI, such as those in health care. Almost every job contains tasks—drafting, summarizing, scheduling, research, basic data work, routine communication—for which AI is already a substantial productivity tool.

The competition most young workers will experience is not human versus machine but colleague versus AI-augmented colleague. For most young workers, the realistic path to making themselves valuable is not to avoid AI but to become fluent in the technology and combine that with domain judgment, contextual reasoning, and human relationship skills. To this end, schools should emphasize paid co-ops, apprenticeships, and employer-linked projects so students build judgment in real workplaces before they graduate.

Governments should also create targeted tax credits, wage subsidies, and training grants for employers that hire early-career workers into structured, AI-augmented roles. The architecture for this kind of conditional, behavior-linked subsidy already exists in US tax policy. What is missing is a version of these instruments built specifically around early-career AI-augmented work.

Firms, for their part, should stop making hiring decisions based only on short-run cost savings from AI. Young workers are not valuable only for the tasks they perform this quarter. Their value lies in learning, skill formation, institutional memory, and future productivity. Entry-level hiring is not just an expense. It is an investment in the future stock of judgment inside the firm. The most effective AI-augmented senior workforce of the late 2030s will be drawn overwhelmingly from the junior cohort of today. Firms that automate away the learning stage may improve their immediate margins but find themselves, a decade from now, without anyone who understands how their own AI-driven workflows actually behave.

Students graduating this spring and next face a tough labor market in transition. AI fluency is becoming a commodity. Domain expertise without AI fluency is being outpaced. The combination is what is genuinely scarce. The mechanical engineer with knowledge of manufacturing and AI proficiency; the software programmer with knowledge of financial services who is also a whiz at AI—these are the types of people who will be in demand.

Georgios Petropoulos is an assistant professor at the USC Marshall School of Business. His research focuses on the implications of information technologies for innovation, competition policy, and labor markets.

Opinion: 8 former CDC directors: Reform PEPFAR, don’t dismantle it

On Sunday, the World Health Organization (WHO) declared an Ebola outbreak in the Democratic Republic of the Congo and Uganda to be a public health emergency. This outbreak is deadly, with hundreds of cases across at least two countries, including, by report, one American who was working in the area.

At the same time, a cluster of hantavirus cases linked to a Dutch cruise ship in the South Atlantic has killed three and exposed hundreds more.

Read the rest…

Prevalence, Themes, and Partisan Differences in US State Legislator X Posts Mentioning Suicide: Content Analysis

Background: Suicide is a leading cause of death in the United States, and state policies can be effective tools to prevent suicide. State legislators are increasingly active on social media, communicating about their legislative priorities and signaling information about their knowledge and attitudes about issues. Objective: This study aimed to characterize US state legislators’ social media posts mentioning suicide on X (formerly Twitter) and explore differences in how Democrat and Republican legislators communicate about suicide. Methods: We used Quorum, a public affairs database, to identify all state legislator X posts mentioning suicide (N=1049) between December 1, 2023, and November 30, 2024. We developed a codebook and used content analysis to characterize posts and document the frequency of communication about suicide and themes related to causes, solutions, and consequences of suicide. We assessed concordance between the social media post language used and guidelines for reporting about suicide. We conducted univariate analysis and chi-square tests to assess differences in the content of posts between Democrat and Republican legislators. Differences in the frequency of posts about suicide were analyzed using 2-tailed tests. Results: Of 1049 posts identified, 849 (80.9%) were included in the final sample. The annual suicide post rate per 10,000 posts was 13.2 (0.1% of all posts) among Democrats and 7.4 (0.1% of all posts) among Republicans (=.09). Suicide related to a specific population was identified in 52.2% (443/849) of posts, with youth, veterans, firearm owners, and the LGBTQ+ (lesbian, gay, bisexual, transgender, queer, and more) population being identified most frequently. Causes of suicide were identified in 37.1% (315/849) of posts, with no significant difference between Democrats and Republicans. However, the types of causes identified varied, with Democrats more likely to identify lethal means (eg, firearms) as a cause of suicide than Republicans (115/573, 20.1% vs 20/172, 7.5%; <.001). About two-thirds (558/849, 65.7%) of posts identified at least one solution to prevent suicide, with Democrats more likely to identify a solution than Republicans (443/573, 77.3% vs 114/268, 42.5%; <.001). General awareness was the most frequent solution, while policy-specific solutions were present in only 23.3% (198/849) of posts. Collateral consequences of suicide were infrequently mentioned. Conclusions: This study found differences between Democrats and Republicans in their X posts about suicide and areas of misalignment with research evidence. When considered within the context of research on the epidemiology of suicide and evidence supporting suicide prevention policies, the study highlights the need to improve communication about suicide with state legislators and to encourage further collaboration with suicide prevention organizations and experts. Furthermore, given the differences observed, study findings suggest potential value in tailoring messages about suicide for legislators based on their political party.

Role of psychological resilience and psychological distress in linking fear of disease progression to quality of life in chronic heart failure: a cross-sectional serial mediation analysis

ObjectiveTo examine whether psychological resilience and psychological distress serially mediate the association between fear of disease progression and quality of life (QoL) in patients with chronic heart failure (CHF).MethodsThis cross-sectional study enrolled 212 patients with CHF admitted between June 2023 and June 2025. Assessment tools included a demographic questionnaire, the Fear of Progression Questionnaire (FoP-Q), the Connor–Davidson Resilience Scale (CD-RISC), the Depression Anxiety Stress Scales-21 (DASS-21), and the Minnesota Living with Heart Failure Questionnaire (MLHFQ). Correlation and serial mediation analyses were performed using IBM SPSS Statistics for Windows, version 22.0, and the PROCESS macro, with the bootstrap method (5,000 resamples) used to test the mediation effects.ResultsThe mean scores were 43.60 ± 8.32 for FoP-Q, 52.71 ± 14.28 for CD-RISC, 44.29 ± 10.68 for DASS-21, and 48.63 ± 10.85 for MLHFQ. Correlation analysis indicated that FoP was negatively correlated with psychological resilience (r = −0.775) and positively correlated with psychological distress and MLHFQ scores (r = 0.868 and 0.773, respectively; all P < 0.05). Psychological resilience was negatively correlated with both psychological distress and MLHFQ scores (r = −0.728 and −0.744, respectively), while psychological distress was positively correlated with MLHFQ scores (r = 0.745; all P < 0.05). The mediation model revealed a direct effect of FoP on QoL (effect = 0.629, 41.14%), along with three indirect pathways: via psychological resilience alone (effect = 0.508, 33.22%), via psychological distress alone (effect = 0.344, 22.50%), and via the serial pathway from psychological resilience to psychological distress (effect = 0.048, 3.14%).ConclusionPatients with CHF exhibited elevated levels of FoP and generally reduced QoL. Psychological resilience and psychological distress served as significant serial mediators in the relationship between FoP and QoL. FoP could directly reduce QoL in patients with CHF and indirectly affect it by decreasing psychological resilience and exacerbating psychological distress. Clinical attention should be directed toward assessing the psychological status of patients with CHF, improving psychological resilience, alleviating negative emotions, reducing the adverse impact of FoP, and enhancing patients’ QoL.

Prediction of 30-Day All-Cause Hospital Readmissions Using Limited Structured Electronic Health Record Data: Retrospective Comparative Study

Background: Unplanned hospital readmissions represent a critical operational and financial challenge for health care systems in the United States, with 3.8 million 30-day all-cause readmissions in 2018 at an average cost of US $15,200 each, totaling US $58 billion in costs. Many published prediction models rely on comprehensive information (eg, full billing abstractions, discharge summaries, laboratory tests, and vitals) that becomes available only late in the encounter, limiting usefulness for real-time, in-hospital intervention. This creates a timeliness-accuracy trade-off: models that are most accurate retrospectively may arrive too late to act upon. Objective: This study tests whether a clinically meaningful predictive signal for 30-day all-cause readmission is present within a limited set of structured clinical codes recorded during the patient’s hospital stay. This approach evaluates whether predictive signals are retained when using a restricted set of structured clinical codes. Methods: We conducted a retrospective comparative modeling study using a large, deidentified electronic health record dataset of 50,000 inpatient encounters from the 2019 New York State Emergency Department Database. Two feature sets were constructed: (1) a limited set consisting of the first 5 () diagnosis codes, the first 5 Current Procedural Terminology (CPT) codes, and Charlson Comorbidity Index (CCI; 11 input features); and (2) a rich set using all available and CPT codes plus CCI (up to 135 input features). We trained 4 models: random forest, CatBoost, multilayer perceptron, and DistilBERT (a distilled Bidirectional Encoder Representations from Transformers [BERT] model; structured codes mapped to text and tokenized with DistilBERT-base-uncased). Evaluation used an untouched hold-out set of 10,000 encounters, preserving the natural 21.1% readmission prevalence. Primary metrics were area under the receiver operating characteristic curve (AUROC), -score, and accuracy. To address class imbalance, the training split only was balanced via undersampling of the majority class and bootstrap oversampling of the minority class; validation/test distributions were left unchanged. Results: Models trained on the limited feature set achieved AUROC values ranging from 0.5369 to 0.5596 and -scores from 0.2555 to 0.3434. Across 3 of 4 architectures, models trained on the limited feature set matched or exceeded the discrimination of their rich counterparts. The best model (random forest, limited) achieved an area under the curve AUROC 0.5596 (95% CI 0.5440‐0.5739) compared to the best performing rich model (DistilBERT) at 0.5703 (95% CI 0.5565‐0.5842), an absolute difference of 0.0107. The highest -score (0.3434) was achieved by DistilBERT on the limited feature set. Differences across architectures were small in absolute terms, with threshold-dependent metrics (eg, -score) being comparable. Conclusions: The findings suggest that models using a limited set of structured clinical codes can achieve performance comparable to those using more comprehensive coding information.
<img src="https://jmir-production.s3.us-east-2.amazonaws.com/thumbs/2c6a3535f15393463cd4b4c04e53b2e6" />

Parabilis Files for IPO, a Day After Signing Up-to-$2.3B Regeneron Collaboration

Parabilis Medicines, the developer of drugs and antibody-drug conjugates targeting historically undruggable protein targets and based on stabilized helical peptides or Helicons™, has filed for an initial public offering (IPO), joining a growing parade of companies seeking to raise capital by tapping into the improving market for first time biotech stocks.

The company’s IPO filing came a day after Parabilis inked an up-to-$2.3 billion-plus strategic research collaboration with Regeneron Pharmaceuticals to discover and develop an initial five candidates encompassing “antibody-Helicon conjugates,” a new form of antibody-drug conjugates aimed at challenging and historically undruggable targets.

Regeneron has agreed to purchase approximately $75 million of Parabilis common stock in a concurrent private placement, at 90% of the IPO price per share.

It’s too soon to know how much money Parabilis plans to raise through the IPO. The company’s Form S-1 registration statement, filed Tuesday with the U.S. Securities and Exchange Commission (SEC), includes a placeholder “$100 million” figure that will inevitably be revised, and doesn’t say how many shares will be sold. Parabilis has applied to list its shares on The Nasdaq Global Market under the ticker symbol “PBLS.”

It’s also too early to know how much of the proceeds will go toward the four priorities it highlighted in its registration statement. Two of the four priorities relate to Parabilis’ lead Helicon peptide candidate zolucatetide (formerly FOG-001), a first and only direct inhibitor of the elusive β-catenin:TCF interaction, according to the company. Parabilis stated that it plans to continue ongoing clinical development of zolucatetide in desmoid tumors, including continuation of dose expansion and the launch of a Phase III registrational trial to topline data.

Parabilis also plans to continue ongoing clinical development of zolucatetide across several additional indications, including dose escalation and expansion in familial adenomatous polyposis (FAP); hepatocellular carcinoma, the most common type of primary liver cancer; and other rare tumors, with the aim of collecting data to support a registrational trial.

‘Expansive opportunity’

“We believe zolucatetide provides clinical validation of our first-in-industry Helicon approach and represents an expansive opportunity for medical and commercial impact,” Parabilis stated.

In addition, Parabilis plans to use IPO proceeds toward advancing its pipeline of additional programs—including its ERG protein degrader, an allosteric androgen receptor in its active state (ARON), and beta-catenin degraders—to Phase I clinical data; toward continued evolution of the Helicon platform for discovering and developing drug candidates; as well as toward general corporate purposes that include additional development efforts, working capital, and operating expenses.

According to Parabilis, zolucatetide has been evaluated in more than 150 patients to date and has generated positive clinical data in solid tumors characterized by alterations in the Wnt/beta-catenin pathway. In the drug’s lead indication of desmoid tumors, researchers have seen tumor reductions in 100% of patients with a 74% objective response rate (ORR) in patients who have had at least two post-baseline scans.

In March, Parabilis presented preliminary clinical data at the 11th Biennial Meeting of the International Society for Gastrointestinal Hereditary Tumors (InSiGHT) showing significant improvement in duodenal polyposis at 60 weeks in a patient with familial adenomatous polyposis (FAP) treated with zolucatetide in the company’s ongoing Phase I/II trial (NCT05919264).

The patient showed a 52.2% reduction in desmoid tumor diameter, as well as “substantial” reductions in polyp number and size compared with a pre-treatment evaluation nearly two years prior, consistent with downstaging from Spigelman stage II to stage I.

Parabilis says its Helicon discovery platform allows it to precisely tune potency, selectivity, and pharmacologic properties by integrating ligands and additional functionalities at multiple positions. The platform integrates artificial intelligence (AI)- and physics-based computational modeling with high-throughput peptide synthesis and experimental screening.

“While our initial programs are focused on disrupting protein-protein interactions and inducing targeted protein degradation, we believe our platform can incorporate other advances in small molecule drug design and extend them to targets that are likely to remain out of reach for other modalities,” Parabilis stated.

Parabilis was founded in 2015 as FogPharma to commercialize technology developed in and inlicensed from the lab of Harvard University researcher and serial entrepreneur Gregory Verdine, PhD. The company, which rebranded itself into Parabilis in 2024, says it has generated proprietary datasets, comprising millions of data points for hundreds of thousands of Helicons across dozens of drug-like properties, following a decade of Helicon drug discovery.

‘Continuous learning loop’

“These data power a continuous learning loop that refines our models from target selection through lead optimization, enhancing our speed, precision, and ability to generate high quality molecules against difficult targets,” Parabilis explained. “As a result, our platform produces unique complex synthetic molecules at scale and a compounding advantage that we believe is difficult to replicate.”

If it carries out the planned IPO, Parabilis would be the 12th biotech to go public this year. The 11 IPO companies to date have raised a combined $3.491 billion, compared to the $1.556 billion raised by 11 companies this time last year. Six of the 11 companies have seen their shares rise since their initial offerings, led by the 520% share price increase of Veradermics, a developer of treatments for dermatology and aesthetic conditions that closed Wednesday at $105.32 a share.

This year’s largest IPO—and the largest of any biotech—was the $625 million offering of Kailera Therapeutics, a developer of therapies for obesity and weight management based on glucagon-like peptide receptor 1 (GLP-1) agonists, alone or in combination with glucose-dependent insulinotropic polypeptide (GIP) receptor agonists.

Kailera last month completed what grew into a $718.75 million IPO last month that generated an estimated $662.1 million in net proceeds through the sale of 44,921,875 shares of common stock—including the exercise in full by underwriters of their option to purchase 5,859,375 additional shares—at the IPO price of $16 per share.

Should Parabilis’ planned IPO raise the placeholder $100 million amount, it would increase by 30% the $329.039 million in cash and cash equivalents that the company reported as of March 31.

Parabilis disclosed in its IPO filing that it ended the first quarter with a $45.316 million net loss, up 18% from its $38.342 million net loss of Q1 2025—as well as a net loss of $145.9 million for last year, up nearly 24% from its $117.9 million net loss for 2024. The company has no reported revenue.

Parabilis’ accumulated deficit rose 8% during Q1, to $586.82 million from $541.504 million at the end of 2025.

To fund its operations, Parabilis reported, it has raised a total $876.8 million as of March 31. That total consisted of $811.8 million from sales of its convertible preferred stock, $15 million in borrowings under a term loan and a $50 million Simple Agreement for Future Equity (SAFE).

The IPO comes just four months after Parabilis completed its last financing, an oversubscribed $305 million Series F round completed in January and co-led by investment firms RA Capital Management, Fidelity Management & Research Co., and Janus Henderson Investors.

Five investment firms were listed in the Form S-1 as underwriters for the IPO: Leerink Partners, BofA Securities, Evercore ISI, Guggenheim Securities, and LifeSci Capital.

The post Parabilis Files for IPO, a Day After Signing Up-to-$2.3B Regeneron Collaboration appeared first on GEN – Genetic Engineering and Biotechnology News.

How Colorectal Tumors Escape KRAS Inhibitors Identified

Researchers at University of Texas MD Anderson Cancer Center and Weill Cornell Medicine have identified key mechanisms that allow colorectal tumors to resist KRAS inhibitors, uncovering both genetic and non-genetic pathways that help cancer cells survive treatment.

The findings, published in Cancer Cell, suggest that combining KRAS inhibitors with therapies targeting early inflammatory responses may improve outcomes for patients with KRAS-mutant colorectal cancer.

KRAS mutations remain difficult to treat in colorectal cancer

KRAS is one of the most commonly mutated oncogenes in colorectal cancer, occurring in nearly half of all patients. Mutations in the gene drive tumor growth by continuously activating signaling pathways involved in cell proliferation and survival.

Although KRAS inhibitors such as Adagrasib and Sotorasib have transformed treatment options for some lung cancers, their clinical benefit in colorectal cancer has been more limited. Many patients either fail to respond or rapidly develop resistance after an initial response.

Previous studies have suggested that tumors may escape treatment by acquiring secondary pathway mutations, but the full picture of resistance has remained unclear.

To investigate this further, the research team analyzed patient-matched tumor samples collected before treatment, during KRAS inhibitor therapy, and after disease progression. The researchers combined targeted gene sequencing with single-cell spatial transcriptomics to examine how tumor cells evolved over time.

The team also used organoid models of KRAS inhibitor-resistant colorectal cancer to validate their findings experimentally.

Tumors evade KRAS inhibition through multiple mechanisms

The researchers discovered that resistant tumors do not rely on a single escape mechanism. Instead, colorectal cancer cells use both genetic mutations and adaptive cell-state changes to survive therapy.

Some resistant cancer cells acquired secondary mutations that bypassed KRAS blockade, while others altered their cellular behavior without acquiring new mutations. According to the authors, these non-genetic adaptations enabled tumor cells to tolerate treatment and remain viable despite continued KRAS inhibition.

Both resistance mechanisms could coexist within the same tumor, highlighting the complexity and heterogeneity of treatment resistance in colorectal cancer.

“Our findings uncovered the genetic and cell-state shifts that colorectal tumors use to escape KRAS inhibition,” said co-lead author Salvador Alonso Martinez, MD, assistant professor of Gastrointestinal Medical Oncology at MD Anderson.

“Targeting the adapted early inflammatory response may be the key to stopping resistance and improving the effectiveness of KRAS therapies for these patients,” he added.

Early inflammatory signaling helps cancer cells survive

One of the study’s most significant findings was the identification of an early inflammatory response triggered shortly after KRAS inhibitor treatment begins.

In tumor samples collected early during therapy, the researchers observed activation of inflammation-related signaling programs that appeared to help cancer cells adapt to therapeutic stress.

Rather than immediately dying in response to KRAS blockade, some tumor cells entered a survival state driven by inflammatory signaling pathways. This adaptive response allowed them to persist and eventually contribute to disease progression.

The investigators identified the protein kinase TBK1 as a central mediator of this inflammatory adaptation.

TBK1 is known to regulate innate immune and inflammatory signaling pathways, but the new findings suggest it may also play a critical role in enabling colorectal tumors to survive KRAS inhibition.

When the researchers blocked TBK1 activity in preclinical models, the inflammatory survival response was suppressed and tumor cells became more sensitive to KRAS inhibitors.

Combination therapy may improve treatment durability

The results suggest that combining KRAS inhibitors with TBK1 blockade could represent a new therapeutic strategy for patients with KRAS-mutant colorectal cancer.

Rather than focusing exclusively on secondary genetic mutations after resistance has already emerged, targeting the early adaptive inflammatory response may help prevent or delay resistance from developing in the first place.

In preclinical organoid models, dual inhibition strategies enhanced treatment sensitivity and overcame resistance mechanisms that limited the effectiveness of KRAS inhibition alone.

The study’s authors believe this approach could potentially produce more durable responses in patients, though clinical validation will still be required.

Implications for future colorectal cancer treatment

The findings add to growing evidence that cancer drug resistance is often driven not only by permanent genetic evolution, but also by reversible adaptive cell states that emerge under therapeutic pressure.

Understanding these early adaptive mechanisms may help researchers design combination therapies that suppress tumor survival pathways before resistant clones become dominant.

The study also demonstrates the increasing importance of single-cell and spatial transcriptomic technologies in oncology research, allowing scientists to observe how tumors dynamically respond to treatment at high resolution.

While TBK1 inhibitors are not yet standard therapies for colorectal cancer, the researchers believe their work provides a strong rationale for future clinical trials combining TBK1 blockade with KRAS-targeted therapies.

If successful, these strategies could expand the clinical impact of KRAS inhibitors in colorectal cancer, where durable responses have historically been difficult to achieve.

The post How Colorectal Tumors Escape KRAS Inhibitors Identified appeared first on Inside Precision Medicine.